
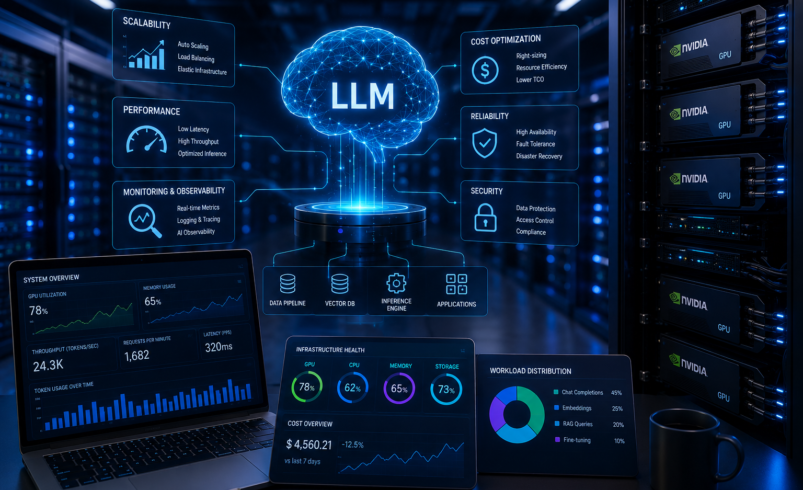

Large Language Models are changing how enterprises build applications, automate processes, and deliver intelligent services. However, successful AI deployment depends on more than selecting the right model. The infrastructure supporting an LLM has a direct impact on performance, scalability, reliability, and operating cost. As AI workloads become larger and more complex, organizations need an AI Infrastructure strategy that can support increasing model sizes, higher request volumes, longer context windows, and demanding latency requirements. Infrastructure that works for an early proof of concept may not be suitable for a production environment.
This is where Infratailors.ai can play an important role. By focusing on AI workloads, infrastructure performance, GPU utilization, and optimization, Infratailors.ai helps organizations think about infrastructure as a core part of their AI strategy rather than simply a resource layer.
Why AI Infrastructure Matters for Enterprise LLMs
An LLM application depends on several infrastructure components working together. GPUs provide the computational capacity required for inference, while memory determines how efficiently models and active requests can be handled. Networking, storage, orchestration, and workload scheduling also influence overall performance.
When one component becomes a bottleneck, the entire application can suffer.
For example, an enterprise may have powerful GPUs but still experience slow responses because of inefficient scheduling or insufficient memory. Another organization may deploy excessive GPU capacity and achieve good performance while paying significantly more than necessary.
Effective AI Infrastructure connects workload requirements with the resources needed to deliver consistent performance.
Start With Workload Requirements
Infrastructure decisions should begin with the workload rather than the hardware.
An enterprise chatbot, document-processing application, coding assistant, and AI agent can have completely different infrastructure requirements.
A customer-facing chatbot may prioritize low latency, while a document-processing workflow may prioritize throughput. An AI agent may make multiple model calls for a single user request, increasing both compute and memory requirements.
Before selecting infrastructure, teams should understand request volume, concurrency, context length, response requirements, model size, and expected workload growth.
This workload-first approach helps organizations avoid overprovisioning and creates a stronger foundation for scalable AI deployment.
GPU Selection Is Only One Part of the Strategy
GPUs are central to modern AI Infrastructure, but choosing a GPU based solely on specifications can lead to poor decisions.
GPU memory, compute capability, memory bandwidth, interconnect performance, and workload compatibility all influence real-world performance.
A model may technically fit on a particular GPU but perform poorly when multiple users access it simultaneously. Another configuration with a different memory capacity or architecture may provide better results for the same workload.
Organizations should therefore benchmark realistic workloads before making major infrastructure commitments.
Infratailors.ai focuses on this type of infrastructure thinking, helping businesses evaluate AI workloads against the resources required to run them efficiently.
GPU Memory Can Become a Hidden Bottleneck
Model weights are only one part of GPU memory consumption.
During inference, memory is also required for the KV cache, intermediate operations, runtime processes, and concurrent requests. Longer prompts and larger context windows can increase memory requirements significantly.
This means a deployment that performs well during a small test may experience memory pressure when production traffic increases.
Effective AI Infrastructure planning should consider model size, precision, context length, concurrency, and memory utilization together.
Monitoring memory behaviour can also help teams determine whether they need larger GPUs, better workload scheduling, quantization, or other optimization techniques.
Improve GPU Utilization
Having more GPUs does not automatically mean having better AI performance.
If GPUs remain underutilized, organizations may be spending heavily on capacity that provides limited value. On the other hand, excessive utilization without sufficient headroom can create latency and reliability problems.
The objective should be balanced utilization.
Workload scheduling, batching, request routing, and capacity management can help distribute AI workloads more efficiently.
Continuous measurement is important because utilization patterns can change as applications gain users.
Infratailors.ai helps organizations examine infrastructure performance from a workload perspective, enabling teams to identify opportunities for better resource utilization and more efficient AI operations.
Inference Optimization for Better Performance
Inference is where infrastructure performance becomes visible to users.
When an LLM generates a response, several factors affect how quickly the result is delivered. Model size, prompt length, GPU performance, batching, memory availability, and concurrency can all influence latency.
Optimization should therefore focus on the complete inference pipeline.
Organizations can evaluate different model configurations, inference engines, quantization approaches, batching strategies, and hardware combinations to identify the most effective setup.
The best configuration is not necessarily the one with the highest theoretical performance. It is the configuration that delivers the required application performance at an acceptable operational cost.
Scaling AI Infrastructure With Demand
Enterprise AI workloads rarely remain constant.
An application may start with a small internal user base and later become an important business service. Request volumes can increase rapidly, particularly when AI capabilities are integrated into customer-facing applications.
Infrastructure must therefore be designed for growth.
Scaling strategies should consider GPU availability, model loading times, memory capacity, workload queues, and expected demand.
Organizations also need to avoid scaling blindly. Adding infrastructure without understanding the actual bottleneck can increase costs without improving application performance.
Observability and workload analysis should guide scaling decisions.
AI Infrastructure and Cost Optimization
GPU infrastructure can represent a significant portion of enterprise AI spending.
Cost optimization does not necessarily mean using cheaper hardware. It means ensuring that available resources are being used efficiently.
Right-sizing GPU capacity, improving utilization, optimizing model configurations, managing concurrency, and eliminating unnecessary workloads can all contribute to lower operating costs.
Organizations should also evaluate cost at the workload level.
Understanding how much infrastructure is required for each application makes it easier to identify inefficient deployments.
Infratailors.ai helps enterprises approach infrastructure optimization with a focus on workload requirements, resource efficiency, and scalable AI operations.
The Role of AI Observability
AI Infrastructure optimization requires reliable performance data.
Traditional server monitoring provides useful information about CPU, memory, and availability, but LLM applications require deeper visibility.
Teams need to understand GPU utilization, GPU memory, inference latency, throughput, request queues, token usage, and workload distribution.
AI observability connects these signals and helps engineering teams understand why performance changes.
For example, rising latency combined with high GPU utilization may indicate insufficient compute capacity. Rising latency with low GPU utilization may point toward another part of the application or infrastructure stack.
This information allows teams to make better optimization decisions.
Designing Infrastructure for Enterprise Reliability
Performance is only one requirement for production AI.
Enterprise applications also need reliability, security, availability, and predictable operations.
Infrastructure should be designed to handle failures and changing workloads without creating major service disruptions.
Redundancy, workload isolation, monitoring, automated deployment, and appropriate scaling strategies can improve operational resilience.
Security should also be considered throughout the architecture, particularly when AI applications process confidential enterprise information.
A strong AI Infrastructure strategy therefore combines performance optimization with reliability and operational control.
Preparing for Future AI Workloads
AI technology continues to evolve quickly.
New models, inference techniques, GPU architectures, and deployment approaches can change infrastructure requirements over time.
Organizations should avoid building infrastructure around assumptions that may become outdated.
Flexible architectures allow enterprises to evaluate new models and hardware without completely rebuilding their AI environment.
This is particularly important for businesses expecting AI adoption to expand across multiple departments and applications.
A scalable infrastructure foundation gives organizations more flexibility as workloads evolve.
How Infratailors.ai Supports AI Infrastructure Optimization
Building production AI requires close coordination between models, applications, and infrastructure.
Infratailors.ai focuses on helping organizations understand the infrastructure requirements of AI workloads and identify opportunities for improved performance and efficiency.
By considering GPU resources, workload behaviour, scalability, utilization, and infrastructure costs together, enterprises can make more informed decisions about AI deployment.
This approach helps organizations move beyond simply acquiring infrastructure and instead develop an environment designed around actual AI workload requirements.
For businesses expanding their use of LLMs, this infrastructure-focused approach can support better performance, more predictable costs, and greater scalability.
Conclusion
Modern LLM applications require an infrastructure strategy designed specifically for AI workloads. GPU selection, memory management, inference optimization, workload scheduling, observability, scalability, and cost control all contribute to the final performance of an enterprise AI application.
The most effective AI Infrastructure strategy begins with understanding the workload and continues through continuous measurement and optimization.
Organizations that treat infrastructure as a strategic component of AI deployment can improve resource utilization, reduce unnecessary costs, and build more reliable production systems.
Infratailors.ai helps enterprises approach these challenges through workload-focused infrastructure planning and optimization. As organizations continue scaling LLM applications, investing in efficient AI Infrastructure will become increasingly important for achieving reliable performance, sustainable costs, and long-term AI growth.